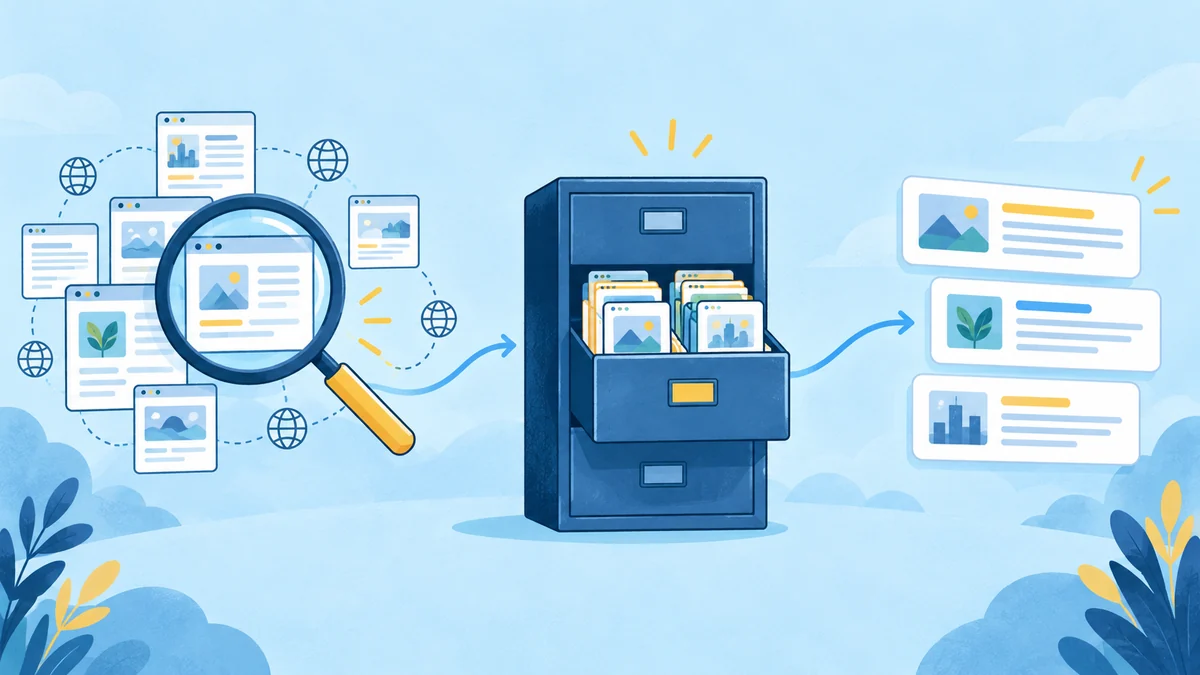
Search engines discover webpages, process their content and select results when someone searches. Crawling is the process of fetching a page. Indexing involves analysing its content and potentially storing it in a search index. Ranking determines which eligible results appear for a particular search and in what order.
These stages explain why publishing a page does not automatically bring visitors. A page might be available on your website but not yet discovered. It might have been crawled without being indexed. It could also be indexed but rarely appear for the searches you want to reach.
When someone tells me, “My website is not showing on Google,” I want to understand which of those situations we are dealing with. Each requires a different investigation. Changing headings or writing more content before checking the actual problem can leave you busy without bringing you closer to an answer.
What is the difference between crawling, indexing and ranking?
Think of these as separate questions about your page, rather than three boxes that every published URL automatically passes through.
| Stage | What it means | The question to ask |
|---|---|---|
| Discovery | A search engine learns that a URL exists | Does the search engine know about this page? |
| Crawling | A crawler requests and fetches the page | Can it access the content? |
| Indexing | The search engine processes the page and may include it in its index | Has this page been included, and which version was selected? |
| Ranking and serving | The search engine selects and orders results for a query | Is this page being shown for relevant searches? |
Google formally describes its process as crawling, indexing and serving search results. Discovery happens before a URL can be fetched, while ranking is part of deciding what to serve. Google also makes clear that crawling, indexing and inclusion in results are not guaranteed. Its explanation of how Google Search works sets out these distinctions.
For your own website, this gives you a more useful starting point than asking whether its “SEO is done.” You can investigate where an important page currently stands and choose work that addresses that situation.
How do search engines discover new pages?
Search engines can discover URLs through links from pages they already know about and through sitemaps. Discovery tells the search engine that an address exists; it does not mean the page has already been visited or added to the index.
Imagine you publish a new service page but do not add it to your navigation, service overview or any relevant article. You can reach it because you have the URL, but someone browsing your website has no obvious route to it.
In a lesson, I would start with a simple exercise: open your homepage and try to reach that service as a potential customer. Where would you click? Does the link describe what you will find? Does it lead directly to the correct page?
That exercise helps you review the website as a connected resource. A page should have a clear place within that structure, rather than existing only because you remember publishing it.
What happens when a search engine crawls a page?
Crawling means requesting a URL and fetching the response. The response might contain a working webpage, a redirect, an error or a restriction that prevents access. Knowing that a URL exists and successfully retrieving its content are different things.
For example, your service page might open normally during one visit but return a server error during another. Before rewriting the content, I would want to understand whether that access problem is temporary, recurring or limited to a particular situation.
This is also where the website’s crawling instructions matter. A robots.txt file can tell compliant crawlers which paths they should not request. However, blocking crawling is not a reliable way to prevent a URL from appearing in Google’s results. Google may still learn about the URL through links without accessing its content. Google’s robots.txt guidance explains this limitation.
Before changing any crawling rule, identify what it controls and why it exists. An instruction affecting one private area is different from a rule preventing access to your main service pages. Removing restrictions without understanding them can create a new problem while you are trying to fix another.
What is rendering, and why does it matter?
Some webpages use JavaScript to load or build important content. Rendering is the process of executing that code and constructing the page, which can reveal content that was not present in the initial HTML response.
Google can render JavaScript, but blocked resources, implementation problems or content that depends on user interaction can complicate what it sees. Google’s JavaScript SEO documentation describes how crawling, rendering and indexing interact.
For a beginner, the practical question is whether the important information is available when the page is processed. If your main service description appears only after a particular interaction, I would investigate that implementation rather than assuming that everything visible in your own browsing session is equally accessible to a crawler.
You do not need to become a developer to recognise the question. You need enough understanding to explain what content matters, identify the evidence that it may be missing and involve someone who can investigate the technical cause.
What does it mean when a page is indexed?
An indexed page has been included in the search engine’s index. That makes indexing different from simply publishing the page in WordPress or successfully opening it in a browser.
One instruction worth understanding is noindex. It tells supporting search engines not to include a page in their search results. Google must be able to crawl the page to see that instruction. Blocking the URL through robots.txt can prevent Google from reading a noindex directive placed on it. Google explains the requirements in its documentation on blocking indexing.
A noindex instruction is not automatically a mistake. You might deliberately keep an unfinished website out of search while preparing it for launch. The important question is whether the instruction matches the purpose and current status of the page.
When reviewing an indexing issue, I would therefore ask, “Should this page be indexed?” before asking how to change its settings. A technical report needs that business context.
Why might Google select a different version of your page?
A website can make the same or very similar content available through more than one URL. Canonicalisation is the process of selecting a representative version from those alternatives.
You can indicate your preferred URL through signals such as a canonical tag, redirects and sitemap inclusion. These signals help Google understand your preference, but declaring a canonical does not force Google to choose it. Google’s canonical URL guidance explains the available methods.
Suppose a product is accessible through its normal address and another URL containing tracking parameters. You would not necessarily want to treat those addresses as two separate pieces of content needing different SEO strategies.
If Google selects an unexpected version, investigate the relationship between the pages and the signals pointing to them. I would compare their content, internal links and canonical settings before recommending a change. The aim is to understand why the website presents multiple versions and whether its preferred version is communicated consistently.
How does Google decide which pages to rank?
Ranking happens in relation to a search. A page does not have one permanent position that applies to every keyword, person and location.
Google describes systems that assess the meaning of a query, the relevance and quality of content, usability and context such as location and settings. The importance of different signals can vary with the search. Its explanation of ranking results outlines these considerations.
Consider two searches: “how to maintain a sewing machine” and “sewing machine repair near me.” A detailed maintenance guide might help the first person. The second may need a local repair service with clear contact details and information about the machines it handles.
When reviewing a page, I would ask whether its content and purpose suit the search you want it to appear for. If your page is a general explanation but the person needs to compare providers, adding the keyword several more times will not fill that gap.
This is where technical understanding connects with content judgement. First establish that the page can be considered for search; then examine whether it provides a suitable answer.
How can you check what Google knows about a page?
Google Search Console’s URL Inspection tool provides information about an individual URL, including its indexed status and available crawl details. You can also run a live test to examine whether the current page can be accessed.
The distinction between those views matters. The indexed information reflects Google’s recorded version, while a live test checks the page now. A successful live test does not prove that the page is indexed or guarantee that it will appear in search results. Google’s URL Inspection documentation explains what each result can tell you.
For a focused review, choose one important URL and record what you find:
- Confirm that you are inspecting the intended page address.
- Read its indexing status and the explanation provided.
- Review the available crawl and canonical information.
- Use a live test when you need to examine the current page.
- Compare the evidence with what the page is intended to do.
Do not change several settings simply because the report contains an unfamiliar label. Write down the observation first, then identify what you still need to investigate.
How I would investigate a page that is not appearing
Imagine a business owner has published a new training page and cannot find it in Google. This is a hypothetical example, but it demonstrates the order in which I would work.
I would first confirm the exact URL and whether the page is intended to be publicly discoverable. Then I would inspect its status rather than assuming it needs more content. If there were an access error, that would become the immediate investigation. If the page were deliberately marked noindex during development, I would confirm whether the website was ready for that instruction to change.
If the intended URL were already indexed, I would move to a different set of questions. Which searches is it meant to serve? Does the page explain the training clearly? Is the target audience obvious? Does the information help someone decide whether the training suits them?
This follows the approach I use in my practical SEO coaching: observe, confirm, investigate and recommend. The recommendation should follow the evidence, rather than being chosen before we understand the problem.
Common questions about crawling, indexing and ranking
Can a page be crawled but not indexed?
Yes. Crawling and indexing are separate stages. A crawl confirms that the search engine fetched the page, but does not mean it included that URL in its index. Investigate the reported status and the page itself before deciding whether the cause involves instructions, duplication, content or another issue.
Does an indexed page automatically rank on the first page?
No. Indexing does not establish a first-page position for your target searches. Once indexing is confirmed, you still need to assess the page’s relevance and usefulness for the searches you want it to serve.
Does requesting indexing guarantee that Google will add my page?
No. An indexing request does not guarantee inclusion. Use it where appropriate after checking the page, but do not treat repeated submissions as a substitute for investigating an unresolved problem.
Should every page on my website be indexed?
No. Decide according to the purpose of each page. An unfinished page, an internal utility page and a useful public service page may need different treatment. The goal is to make the right content available in search, rather than treating the highest possible indexed-page count as a success measure.
What should I learn from this before hiring an SEO agency?
Ask the agency to explain whether a recommendation addresses discovery, access, indexing or search relevance. You do not need to know every technical detail, but you should understand which problem the work is meant to solve and how the agency confirmed it.
For example, “We need to fix indexing” is incomplete without identifying the affected pages, why those pages should be indexed and what the evidence shows.
Learn to identify the stage before choosing the fix
The next time a page is not bringing search traffic, begin with a more precise question than “What is wrong with my SEO?” Establish whether the issue concerns discovery, access, indexing or visibility for relevant searches. That gives your investigation a direction and helps you avoid changes that do not address the problem.
If you want to practise this on your own website, my 1:1 SEO lessons give us space to examine the evidence together. Bring a page you are unsure about, and we can work through what its status means, what needs further investigation and which action makes sense next.